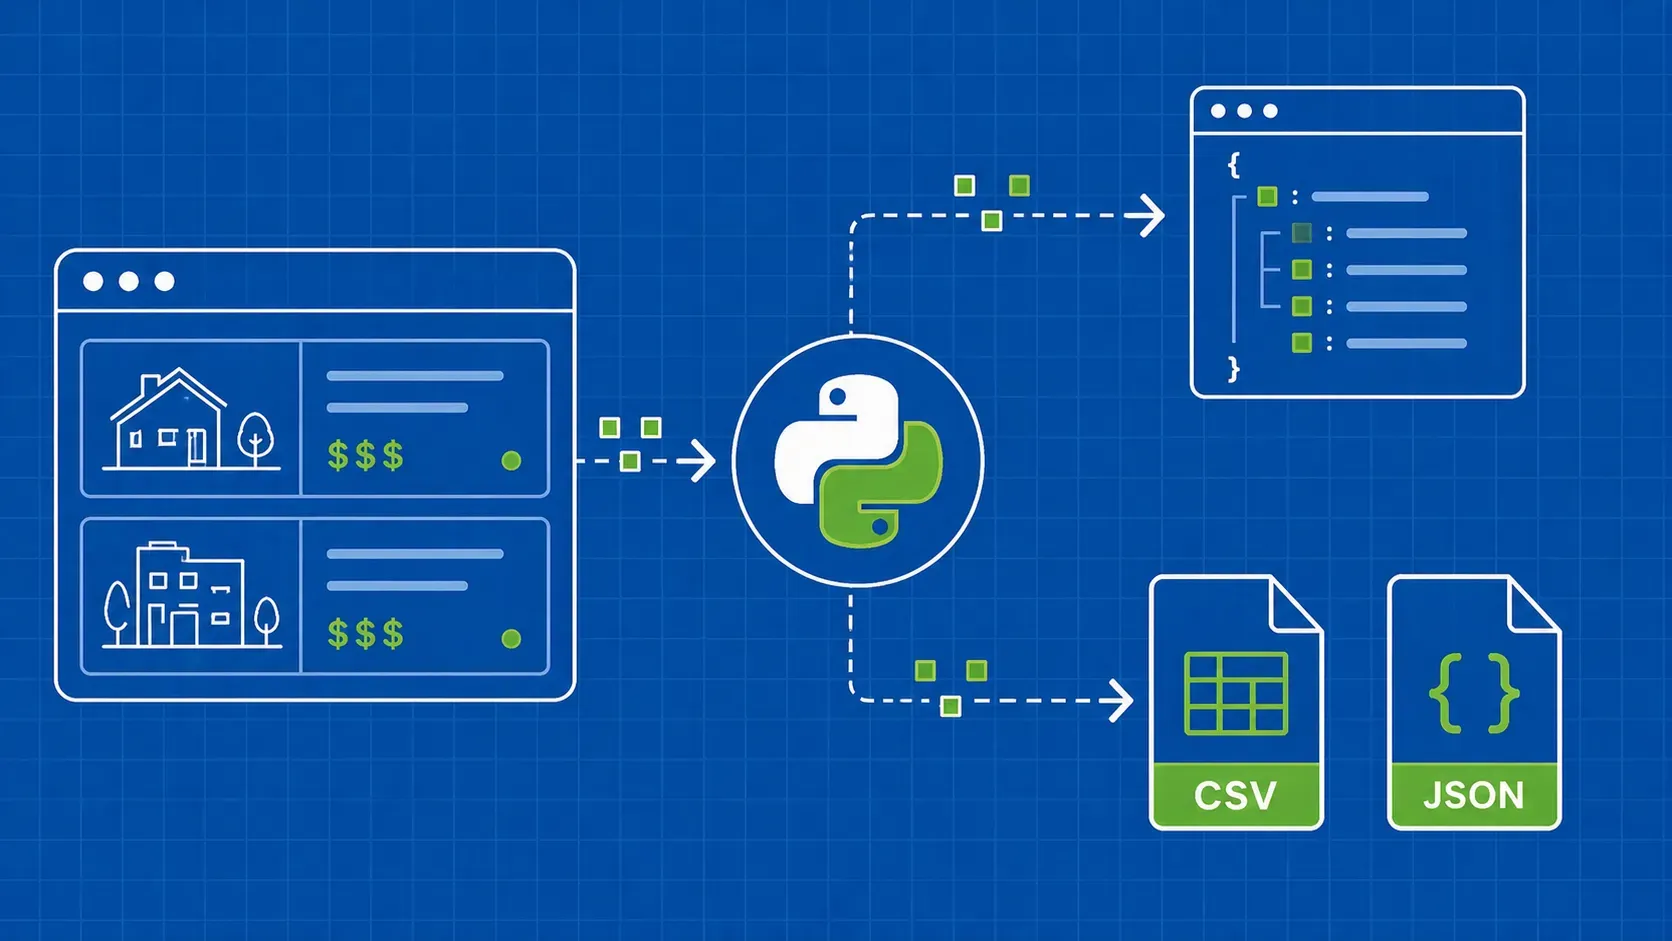
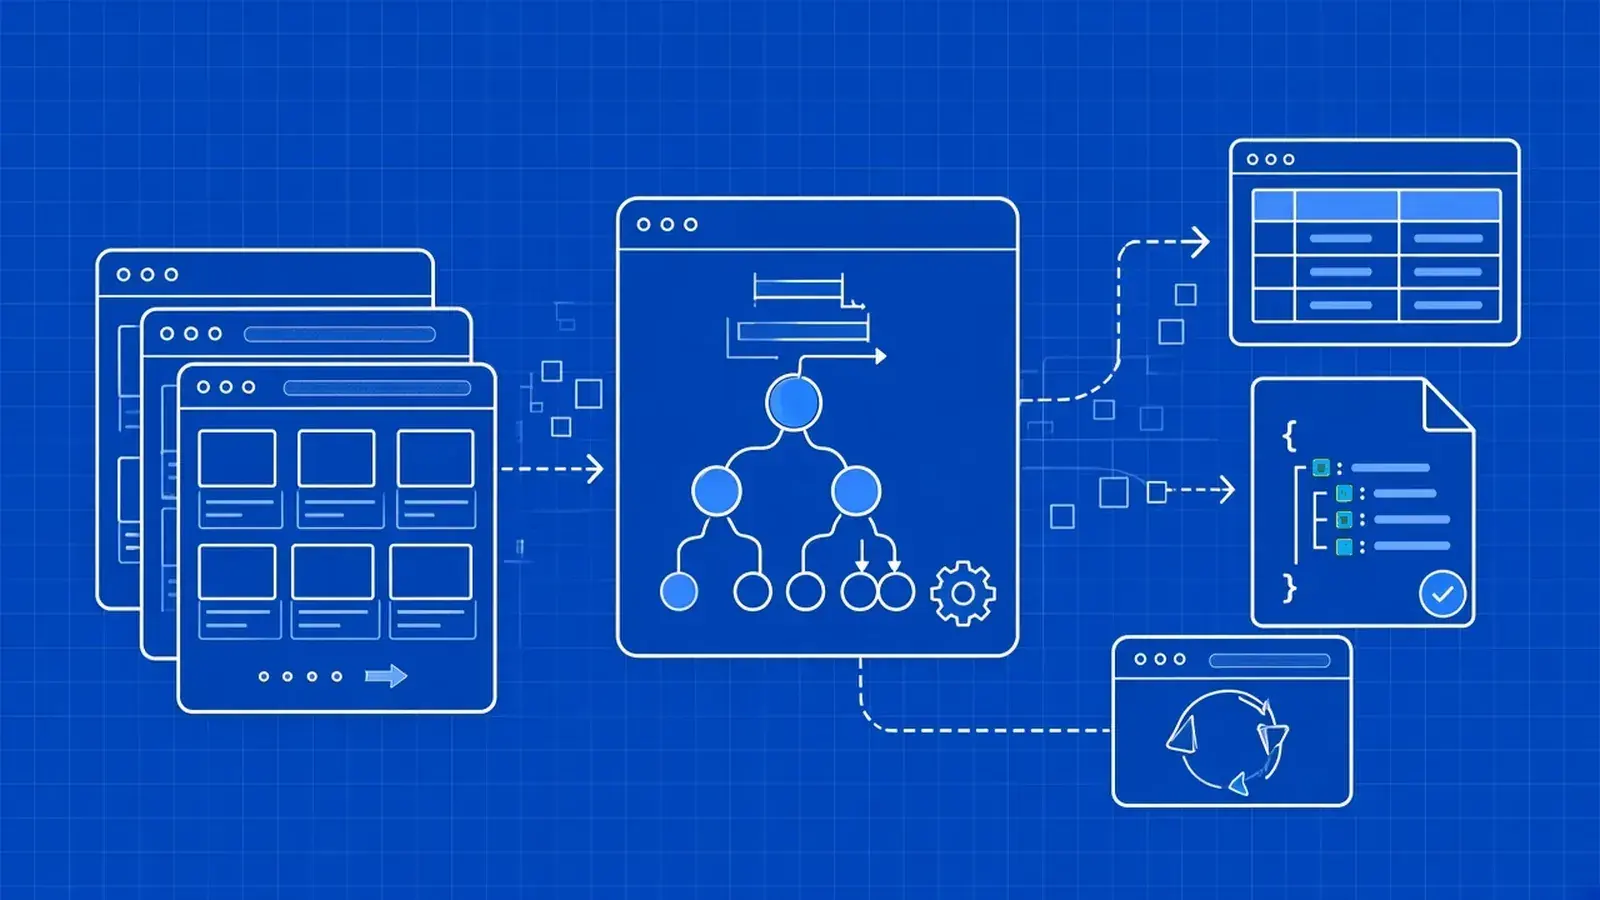
TL;DR: Ruby scrapes the web with Faraday for HTTP, Nokogiri for CSS and XPath parsing, and a small thread pool for concurrency. This guide builds a scraper that crawls a 1,000-book practice catalog into CSV and JSON, retries politely, handles a JavaScript page with Ferrum, and calls a scraping API from the same code.
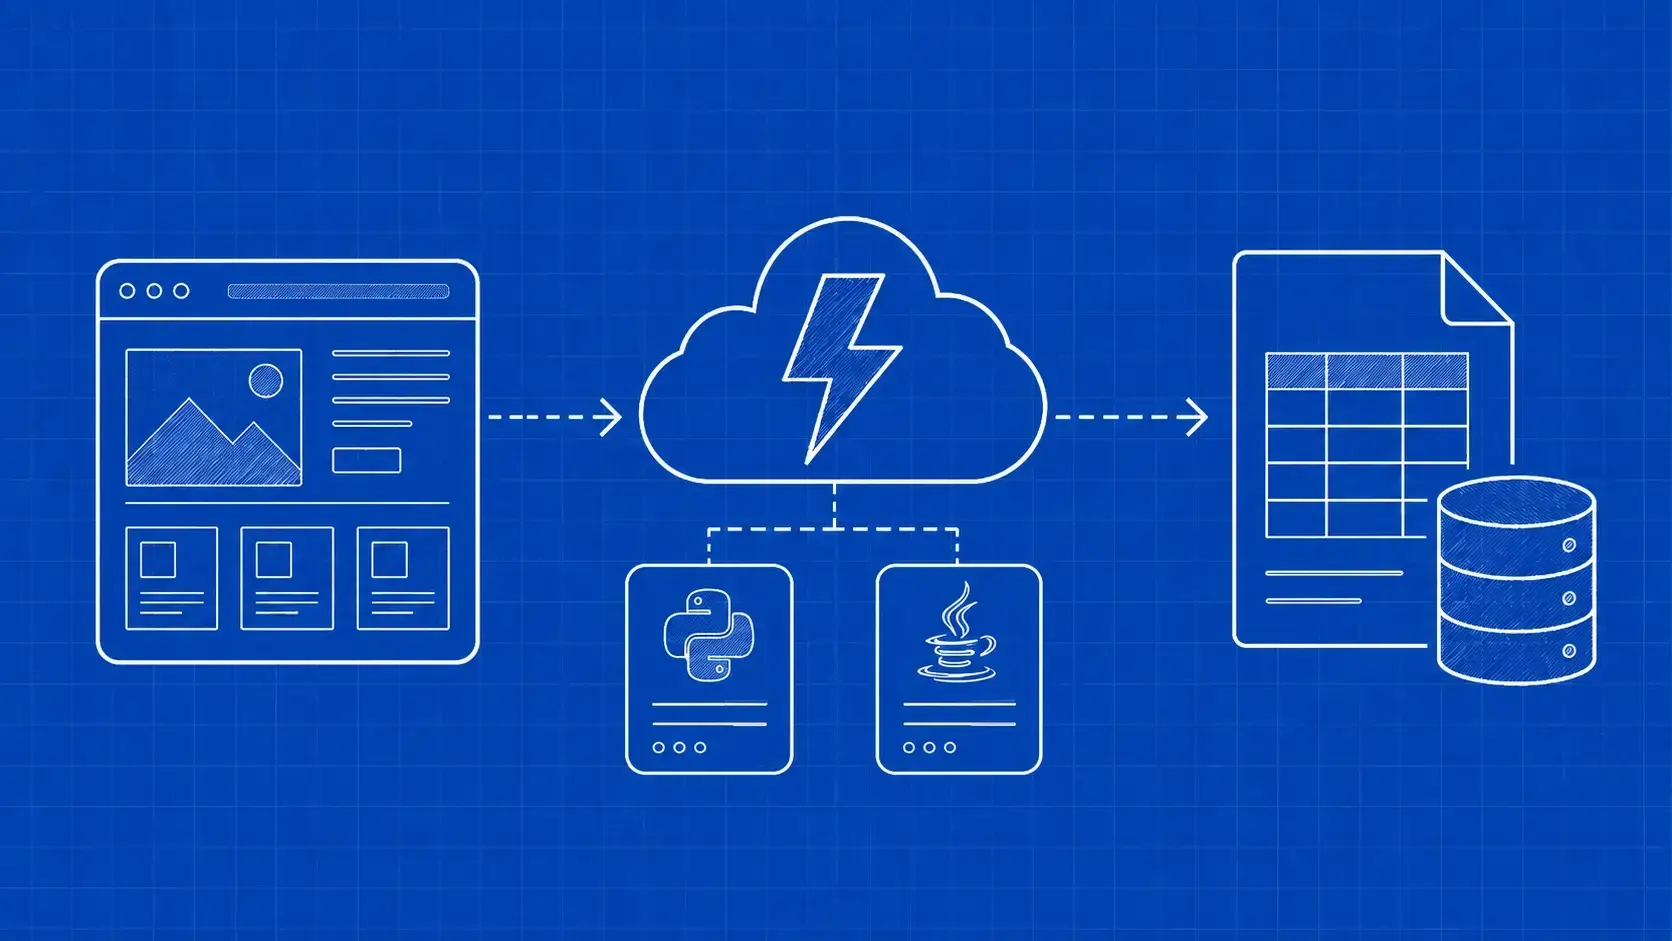
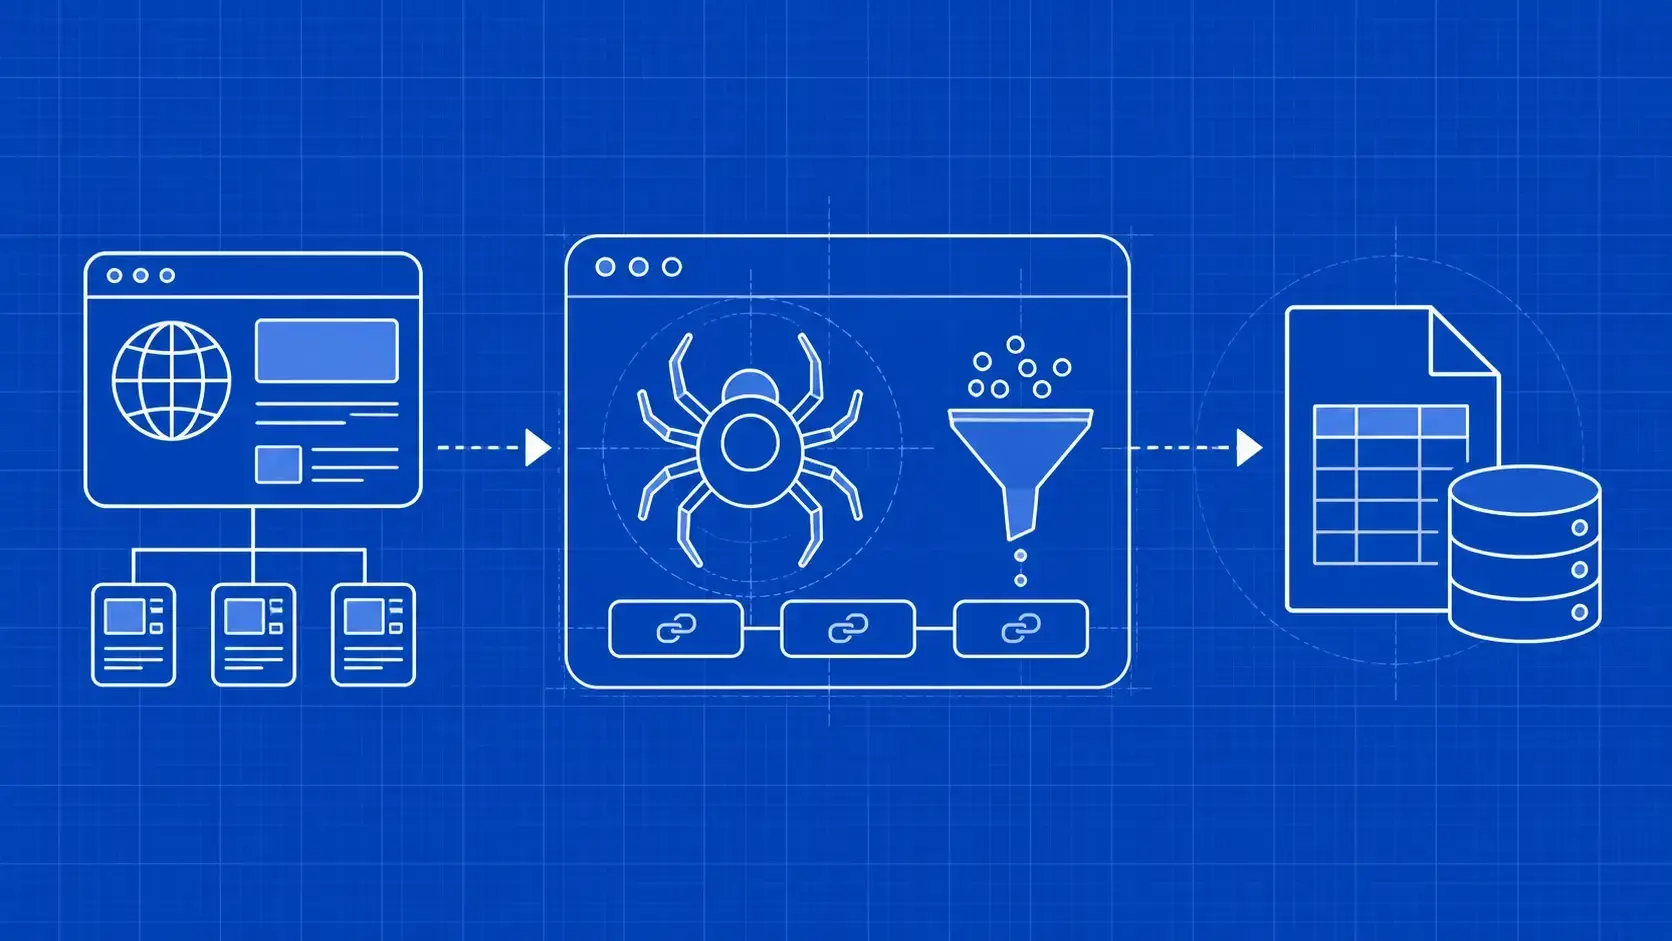
Web scraping with Ruby takes three pieces: Faraday fetches the page, Nokogiri parses the HTML with CSS selectors or XPath, and a fixed pool of threads fetches many pages at once without overloading the site. You'll build one scraper end to end. It collects every book from books.toscrape.com, a public practice catalog, follows the pagination, runs pages concurrently, retries rate-limited requests the right way, and writes the results to CSV and JSON. Then you'll handle a JavaScript-rendered page (quotes.toscrape.com/js/) three ways, log in to a practice form with Mechanize, and call a scraping API from the same Faraday code.
The code targets Ruby 3.4 or newer and the gem versions in the table below.