Skip to content
Start free
Back to Blog

Web Scraping Best Practices: A Lifecycle Playbook With Tips and Working Code

Anda MiuțescuLast updated on 27 min read
Web Scraping Best Practices: A Lifecycle Playbook With Tips and Working Code
TL;DR: Web scraping best practices are the habits that keep a scraper legal, polite, accurate, and cheap to run. Write a data contract, prefer APIs or JSON over HTML, follow robots.txt as RFC 9309 defines it, pace each host, honor Retry-After, and validate every record before saving it. This playbook applies them to each stage of a scraper's lifecycle, with working Python snippets.

Web scraping best practices are the habits that keep a scraper legal, polite, accurate, and cheap to run: plan the data you need, follow robots.txt and site terms, pace requests per host, handle 429s with backoff, parse defensively, validate every record, monitor each run, checkpoint progress, and track cost per valid record.

The guide below applies these best practices for web scraping to each stage of a scraper's lifecycle, from the first plan to the monthly bill, with a short Python snippet wherever code makes the point clearer.

The snippets need Python 3.10 or newer and two libraries:

pip install requests beautifulsoup4

Save each snippet under the file name shown above it and run it from that folder, for example with python polite_fetch.py.

Stage

Goal

Key practice

Section

Plan

Know what "done" looks like

Data contract plus source order

Planning

Legal and polite

Stay welcome

RFC 9309 robots.txt, honest User-Agent

Legal and polite scraping

Rate

Don't overload

Per-host pacing, Retry-After, backoff

Request rate

Requests

Fewer failures

Timeouts, sessions, 304s

Request habits

Blocks

Recover calmly

Diagnose, then escalate one rung

Blocks

Rendering

Pay only when needed

JSON first, browser last

Headless browsers

Parsing

Survive redesigns

Stable hooks, fallbacks, bytes in

Parsers

Data quality

Trust the output

Schema, reject reasons, dedupe

Data quality

Monitoring

Notice first

Run metrics, canaries, exit codes

Monitoring

Scale

Grow without chaos

Frontier, transactional checkpoints

Scaling

Cost

Stay profitable

Cost per valid record

Cost

What are the most important web scraping best practices?

If you only adopt ten habits, make them these: write a data contract, prefer APIs and JSON over HTML, obey robots.txt correctly, identify your bot, pace each host, honor Retry-After, set timeouts, validate records before saving, alert on empty or thin pages, and commit checkpoints with the data they describe.

Each of these ten web scraping best practices links to the section that explains it.

  1. Write a data contract that fixes fields, types, a unique key, and freshness before any code exists.
  2. Prefer an official API or the page's own JSON over parsing HTML.
  3. Apply robots.txt the way RFC 9309 defines it, not the way your library happens to.
  4. Identify your bot with an honest User-Agent and a contact address.
  5. Pace each host separately, starting slow and adapting to the server.
  6. Honor Retry-After and back off exponentially with jitter.
  7. Set connect and read timeouts on every request.
  8. Validate records before saving them and keep the reasons for every reject.
  9. Alert on empty or thin pages, not just on crashes.
  10. Commit checkpoints together with the data they describe, so a crash never leaves a page half saved.

How should you plan a web scraping project?

Plan backwards from the data. Write down the fields, types, freshness, and volume you need, then pick the cheapest reliable source. Rank web scraping techniques by cost: an official API first, then the JSON the page already loads, then sitemaps for discovery, then static HTML, and a headless browser only as a last resort. Budget requests before writing code.

If you're still deciding whether to scrape at all, start with the questions to answer before you write a scraper.

Write a data contract first

A data contract is a short table of exactly what the scraper must deliver. Here's one for a book-price monitor:

Field

Type

Required

Rule

url

string (absolute)

yes

unique key

title

string

yes

non-empty

price

decimal

yes

> 0

currency

ISO 4217 code

yes

e.g. GBP

in_stock

boolean

yes

from availability text

rating

integer 1–5

no

null allowed

fetched_at

UTC timestamp

yes

set by the fetcher

The monitor needs fresh data daily, at about 1,000 rows per run.

The parser fills this contract, validation enforces it, and monitoring alerts when a run falls short.

Pick the cheapest reliable source

Work down this list and stop at the first source that has every field in your contract:

  1. An official API. When a site offers one, pulling data from an API beats parsing HTML: you get stable field names, documented limits, and explicit terms of use.
  2. The JSON the page already loads. Open DevTools, filter the Network tab by Fetch/XHR, and reload. Many sites fetch their data as JSON before drawing it on screen.
  3. Sitemaps, for discovery. Use the site's XML sitemaps to discover URLs instead of crawling every link. Their lastmod dates also show which pages changed since your last run.
  4. Static HTML. Fetch and parse the page when the data is in its source.
  5. A rendered page. Run a headless browser only when the data exists nowhere else.

Each step down costs more requests, more parsing code, and more breakage when the site changes.

Here's step 2 in practice: the JavaScript version of quotes.toscrape.com loads its quotes from a paged JSON endpoint, so you never touch the HTML.

json_endpoint.py

"""Prefer the JSON a page already loads over parsing its HTML."""
import requests

url = "https://quotes.toscrape.com/api/quotes"
page, quotes = 1, []
while True:
    data = requests.get(url, params={"page": page}, timeout=(5, 30),
                        headers={"User-Agent": "acme-quotes-bot/0.1 (+mailto:data@example.com)"}).json()
    quotes += [(q["text"], q["author"]["name"]) for q in data["quotes"]]
    if not data["has_next"]:
        break
    page += 1
print(len(quotes), "quotes from", page, "JSON pages; first:", quotes[0][1])
  • /api/quotes?page=N is the same request the page makes in the browser, found in the Network tab.
  • has_next is the stop condition, so you never guess the last page or fetch empty ones.
  • There's no HTML parser, because the fields arrive named and typed.

Budget requests before writing code

A rough budget shows whether the plan is even possible: pages × frequency ÷ allowed rate = run duration.

Say you need 10,000 product pages a day and the site tolerates one request every two seconds. That's 10,000 × 2 = 20,000 seconds, or about 5.6 hours of crawling per day. If that doesn't fit, you need fewer pages, an incremental crawl, or a source with more records per request. Crawling faster isn't an option, because the site sets the rate.

Keep raw responses for a few days

Store the raw HTML or JSON you fetch for a few days, compressed and keyed by URL and fetch time. A broken selector or a new field then means re-parsing stored copies, not crawling the site again.

How do you scrape a website legally and politely?

Scrape only public data you have a legitimate reason to collect, read the site's terms, and stay out of logged-in areas unless you're permitted. Fetch robots.txt and apply it the way RFC 9309 defines, identify your bot with a contact URL, avoid personal data you don't need, and never impersonate a search engine crawler.

How does robots.txt matching actually work?

The robots.txt file has been a formal standard since 2022, when the IETF published RFC 9309, the Robots Exclusion Protocol. The rules that matter:

  • Find your group first. Groups start with User-agent lines. Your crawler follows the group naming its product token, and the * group applies only if none does.
  • The longest match wins. When several rules match a path, the most specific one (the one with the most characters) decides.
  • Allow wins a tie. If an Allow and a Disallow rule match with equal length, the path is allowed.
  • Two special characters. * matches any sequence of characters and $ anchors the end of the path, so Disallow: /*.pdf$ blocks every URL whose path ends in .pdf.
  • Status codes change the meaning. A 4xx error on robots.txt means a crawler may access everything. A 5xx error or a failed request means it must assume complete disallow.
  • Caching has a limit. Don't keep using a cached copy for more than 24 hours.
  • Crawl-delay isn't in the standard, and Google ignores it. Honor it anyway when it's present, since it states what the site owner wants.

The RFC also says these rules are not a form of access authorization: the file is a published request from the site owner, not a lock.

Why your robots.txt parser may disagree with the standard

Python's urllib.robotparser is the obvious choice for Python scrapers, but it checks rules in file order and stops at the first match instead of picking the longest. It also treats rule paths as plain prefixes, so * and $ mean nothing special.

The snippet below runs one small robots.txt through both approaches and prints their verdicts side by side. The polite fetcher later imports its parse_robots() and rfc9309_allowed() functions.

robots_match.py

"""robots.txt per RFC 9309: pick the group for your user agent, then the
longest matching rule wins, Allow wins ties, '*' matches any characters and
'$' anchors the end of the path."""
import re
import urllib.robotparser


def parse_robots(text, user_agent):
    """Return (rules, crawl_delay) for the group that applies to user_agent."""
    groups, current, in_agent_lines = [], None, False
    for raw in text.splitlines():
        line = raw.split("#", 1)[0].strip()
        if ":" not in line:
            continue
        key, value = (part.strip() for part in line.split(":", 1))
        key = key.lower()
        if key == "user-agent":
            if not in_agent_lines:  # a new group starts
                current = {"agents": [], "rules": [], "delay": None}
                groups.append(current)
            current["agents"].append(value.lower())
            in_agent_lines = True
            continue
        in_agent_lines = False
        if current is None:
            continue
        if key in ("allow", "disallow"):
            current["rules"].append((key, value))
        elif key == "crawl-delay":  # not in RFC 9309, but a clear signal
            try:
                current["delay"] = float(value)
            except ValueError:
                pass
    token = user_agent.split("/")[0].lower()  # product token, e.g. "acme-price-monitor"
    matched = [g for g in groups if token in g["agents"]] or \
              [g for g in groups if "*" in g["agents"]]
    rules = [rule for g in matched for rule in g["rules"]]
    delay = next((g["delay"] for g in matched if g["delay"] is not None), None)
    return rules, delay


def _pattern(rule_path):
    regex = re.escape(rule_path).replace(r"\*", ".*")
    if regex.endswith(r"\$"):
        regex = regex[:-2] + "$"
    return re.compile(regex)


def rfc9309_allowed(rules, path):
    """rules: list of ("allow"|"disallow", path) for the group that applies to you."""
    best_len, verdict = -1, True  # no matching rule means allowed
    for kind, rule_path in rules:
        if not rule_path:
            continue  # an empty Disallow allows everything
        if _pattern(rule_path).match(path):
            length = len(rule_path)
            if length > best_len or (length == best_len and kind == "allow"):
                best_len, verdict = length, kind == "allow"
    return verdict


if __name__ == "__main__":
    robots_txt = """User-agent: *
Disallow: /catalogue/
Allow: /catalogue/category/
Disallow: /*.pdf$

User-agent: acme-price-monitor
Disallow: /checkout/
Crawl-delay: 2
"""
    stdlib = urllib.robotparser.RobotFileParser()
    stdlib.parse(robots_txt.splitlines())
    rules, _ = parse_robots(robots_txt, "mybot/1.0")
    for path in ["/catalogue/category/books_1/index.html", "/catalogue/item_1.html",
                 "/files/report.pdf", "/files/report.pdf?v=2", "/index.html"]:
        print(f"{path:42} RFC 9309: {str(rfc9309_allowed(rules, path)):5}  "
              f"urllib.robotparser: {stdlib.can_fetch('mybot', path)}")
    rules, delay = parse_robots(robots_txt, "acme-price-monitor/1.2 (+https://example.com/bot)")
    print("acme-price-monitor group:", rules, "crawl-delay:", delay)
    print("/catalogue/item_1.html for acme-price-monitor:", rfc9309_allowed(rules, "/catalogue/item_1.html"))

What the comparison shows:

  • /files/report.pdf is allowed by urllib.robotparser, even though Disallow: /*.pdf$ forbids it under the standard, because the stdlib parser reads the * literally.
  • /catalogue/category/books_1/index.html is blocked by urllib.robotparser, because Disallow: /catalogue/ comes first in the file. Under the standard, the longer Allow: /catalogue/category/ wins and the page is allowed.
  • acme-price-monitor has its own group, which replaces the * group entirely. For that bot, /catalogue/item_1.html is allowed with a two-second crawl delay, because none of the * rules carry over.

Use a standards-compliant matcher, or at least test your parser against the specific rules you depend on.

Terms of service, logins, and personal data

A few rules cover most situations:

  • Read the terms first. Logging in usually means accepting them, and many prohibit automated access, so treat authenticated areas as off-limits without permission.
  • Collect the minimum personal data, or none. Skip names, emails, or profile details your data contract doesn't list; data protection laws such as the GDPR apply to personal data whether you scraped it or not.
  • Don't work around paywalls, logins, or CAPTCHAs. They signal that the owner wants to limit access.

These are working habits, not legal advice. For the legal detail, see our guide to whether web scraping is legal.

Identify your scraper honestly

Use a stable User-Agent that names your product, its version, and a way to reach you:

acme-price-monitor/1.2 (+https://example.com/bot; data@example.com)

A site owner who sees unusual traffic from that string can contact you instead of blocking an IP range, and robots.txt authors get a product token to target.

Never send a Googlebot User-Agent. Google documents how site owners can verify its crawlers with reverse and forward DNS lookups or its published IP ranges, so a fake one fails the check and looks deceptive once caught.

How fast can you scrape without overloading a website?

There is no universal safe rate. Start with one or two concurrent requests per host and a pause of about a second, then let the server set the pace: slow down when latency rises, stop and wait when you get a 429 or 503, honor Retry-After, and back off exponentially with jitter.

Budget per host, not per scraper

Ten workers that each pause politely can still send ten parallel requests to one domain. Pace where every request to a host passes through: one fetcher object, or a shared limiter across machines.

Let the server set the pace

Rising latency means the server is working harder, so widen the delay before errors start. Schedule big crawls for the site's off-peak hours, usually night in its main market's time zone.

Handle 429 and Retry-After correctly

429 Too Many Requests (RFC 6585) means you've sent too many requests in a given amount of time, and a 503 means the server is overloaded or down for maintenance. Both may carry the Retry-After header, and HTTP Semantics (RFC 9110) allows two formats for its value:

Retry-After: 120
Retry-After: Fri, 09 Oct 2026 07:30:00 GMT

The first is seconds and the second an HTTP date, and a scraper that handles only one will crash or ignore the header when it meets the other. Treat the value as a minimum wait.

Back off exponentially, with jitter

When there's no Retry-After, or a retry fails again, wait longer each time:

wait = min(cap, base × 2^attempt) × random(0.5 to 1.5)

Use the larger of that wait and any Retry-After value. The random factor is the jitter: without it, workers that failed together retry together and hit the server in one synchronized wave.

Retry only what's retryable

Retry 429, 500, 502, 503, and 504 responses and network timeouts on idempotent GET requests. Don't retry a 404, since the page isn't coming back, or hammer a 403, since the same request gets the same answer. Cap attempts and log every give-up so stuck URLs show up in your metrics.

A polite fetcher in one class

The PoliteFetcher class below combines this section and the next, importing parse_robots() and rfc9309_allowed() from the robots.txt snippet, so keep both files in one folder.

polite_fetch.py

"""A polite, resilient fetcher: robots.txt, per-host pacing, timeouts,
retries with backoff and jitter, Retry-After, and conditional requests."""
import email.utils
import random
import time
from urllib.parse import urlsplit

import requests

from robots_match import parse_robots, rfc9309_allowed  # Snippet 2

USER_AGENT = "acme-price-monitor/1.2 (+https://example.com/bot; data@example.com)"
RETRYABLE = {429, 500, 502, 503, 504}
ROBOTS_TTL = 24 * 3600  # RFC 9309: don't trust a cached copy for more than 24 h


class PoliteFetcher:
    def __init__(self, min_delay=1.0, max_retries=4, timeout=(5, 30)):
        self.session = requests.Session()
        self.session.headers["User-Agent"] = USER_AGENT
        self.min_delay, self.max_retries, self.timeout = min_delay, max_retries, timeout
        self.robots, self.last_hit, self.validators = {}, {}, {}

    def _robots(self, host):
        cached = self.robots.get(host)
        if cached and time.monotonic() - cached[0] < ROBOTS_TTL:
            return cached[1], cached[2]
        try:
            resp = self.session.get(host + "/robots.txt", timeout=self.timeout)
        except requests.RequestException:
            resp = None
        if resp is None or resp.status_code >= 500:
            rules, delay = [("disallow", "/")], None  # unreachable: assume full disallow
        elif resp.status_code >= 400:
            rules, delay = [], None  # unavailable (e.g. 404): no restrictions
        else:
            rules, delay = parse_robots(resp.text, USER_AGENT)
        self.robots[host] = (time.monotonic(), rules, delay)
        return rules, delay

    def allowed(self, url):
        parts = urlsplit(url)
        rules, _ = self._robots(f"{parts.scheme}://{parts.netloc}")
        path = (parts.path or "/") + (f"?{parts.query}" if parts.query else "")
        return rfc9309_allowed(rules, path)

    def _pace(self, host):
        _, crawl_delay = self._robots(host)
        delay = max(self.min_delay, crawl_delay or 0)
        wait = self.last_hit.get(host, 0) + delay - time.monotonic()
        if wait > 0:
            time.sleep(wait)
        self.last_hit[host] = time.monotonic()

    @staticmethod
    def _retry_after(value):
        if not value:
            return None
        if value.isdigit():
            return int(value)
        when = email.utils.parsedate_to_datetime(value)  # HTTP-date form
        return max(0, when.timestamp() - time.time())

    def get(self, url):
        if not self.allowed(url):
            raise PermissionError(f"robots.txt disallows {url}")
        parts = urlsplit(url)
        host = f"{parts.scheme}://{parts.netloc}"
        headers = {}
        etag, modified = self.validators.get(url, (None, None))
        if etag:
            headers["If-None-Match"] = etag
        if modified:
            headers["If-Modified-Since"] = modified
        for attempt in range(self.max_retries + 1):
            self._pace(host)
            try:
                resp = self.session.get(url, headers=headers, timeout=self.timeout)
            except (requests.ConnectionError, requests.Timeout):
                resp = None
            if resp is not None and resp.status_code not in RETRYABLE:
                if resp.status_code == 200:
                    self.validators[url] = (resp.headers.get("ETag"),
                                            resp.headers.get("Last-Modified"))
                return resp  # 200, 304, or a non-retryable error for the caller
            if attempt == self.max_retries:
                break
            backoff = min(60, 2 ** attempt) * random.uniform(0.5, 1.5)
            server_hint = self._retry_after(resp.headers.get("Retry-After")) if resp is not None else None
            time.sleep(max(backoff, server_hint or 0))
        raise RuntimeError(f"gave up on {url} after {self.max_retries + 1} attempts")


if __name__ == "__main__":
    f = PoliteFetcher(min_delay=1.0, max_retries=2)
    for url in ["https://books.toscrape.com/", "https://httpbin.org/etag/abc123",
                "https://httpbin.org/etag/abc123", "https://httpbin.org/status/404"]:
        r = f.get(url)
        print(r.status_code, len(r.content), "bytes", url)
    for url in ["https://httpbin.org/deny", "https://httpbin.org/status/503"]:
        try:
            f.get(url)
        except (PermissionError, RuntimeError) as exc:
            print("expected:", exc)

The key lines:

  • _robots() fetches robots.txt with your own User-Agent, treats a 4xx as "no restrictions" and a 5xx or network error as "stay out", and refetches once the cached copy is 24 hours old.
  • _pace() enforces the delay per host and uses the site's Crawl-delay when it's longer than your own minimum.
  • RETRYABLE limits retries to rate limits and server errors. A 404 goes straight back to the caller.
  • _retry_after() handles both the seconds and HTTP-date forms, and the loop sleeps for whichever is longer, the backoff or the server's hint.

The demo at the bottom gets a 304 on a repeat request, returns a 404 without retrying, refuses a robots-disallowed path before sending it, and gives up on a permanent 503 after its capped attempts.

Which request habits prevent most scraping failures?

Most failures come from sloppy requests, not clever defenses. Always set connect and read timeouts, reuse one session per host, send a consistent and honest header set, accept compression, skip images and fonts you don't need, normalize URLs to avoid duplicates, and use conditional requests so unchanged pages come back as an empty 304.

  • Set separate connect and read timeouts on every request, such as 5 seconds and 30 seconds. In requests, a call without one can wait indefinitely and stall a worker.
  • Use one requests.Session per host. It reuses connections, skipping repeated TLS handshakes and easing the load on the server.
  • Send the same realistic, honest header set on every request, with a User-Agent that identifies you. Our HTTP headers guide for web scraping covers which headers matter and in what order.
  • Keep compression on. requests asks for gzip by default; if you build headers by hand, keep Accept-Encoding, since compressed HTML is a fraction of the size on the wire.
  • Clean URLs before they enter your queue: strip tracking parameters and #fragments, follow rel="canonical" links, and dedupe.
  • Skip tracking pixels and duplicate pagination views; fetch only what you'll parse.

Cache pages and use conditional requests

When a response carries an ETag or Last-Modified header, store it and send it back next time as If-None-Match or If-Modified-Since. With these conditional requests, an unchanged page gets a 304 Not Modified with no body, which saves bandwidth for you and work for the site.

PoliteFetcher.get() already does this: its validators dictionary stores each URL's ETag and Last-Modified from the last 200 response and sends them back next time. A 304 comes back as is, so your code reuses its stored copy.

What should you do when a website starts blocking your scraper?

Diagnose before you escalate. Read the signal (403, 429, 503, or a 200 that serves a CAPTCHA or empty shell), check your own rate and headers first, then climb one rung at a time: slow down, fix headers, add tested proxies, render the page, and finally hand the hard targets to a managed scraping API.

Signal

Likely cause

First response

429 Too Many Requests

Rate limit

Honor Retry-After; lower per-host concurrency

503 with Retry-After

Overload or maintenance

Wait the stated time; back off

403 Forbidden

Blocked IP, header mismatch, or login required

Check headers and terms; don't hammer retries

200 with a challenge or CAPTCHA page

Bot defense

Treat it as a failure in validation; slow down, then escalate

200 with an empty data shell

JavaScript-rendered content

Look for the JSON call; render only if needed

Rising timeouts

Server strain or throttling

Widen delays; reduce concurrency

Unsure what a code means? See our list of proxy and HTTP status errors.

Soft blocks are the dangerous ones: a 200 response holding a challenge page or no data looks like success, and only the data checks later in this guide catch it.

Sites block scrapers because heavy automated traffic strains servers and can hurt the business. OWASP's automated threats list names scraping as its own threat, OAT-011, and most defenses target volume and abuse patterns, so polite, well-identified traffic triggers fewer of them.

Escalate in this order:

  1. Slow down and lower concurrency on the affected host.
  2. Fix your headers so they're consistent and complete.
  3. Add proxies, starting with choosing the right proxy type for the target. Test your proxies before you scale up, then spread load with rotating proxies.
  4. Render the page in a headless browser if the data only appears after JavaScript runs.
  5. Hand the hardest targets to a managed scraping API.

For fingerprinting, CAPTCHAs, and stealth browsers, use our playbook for scraping without getting blocked.

When do you actually need a headless browser?

Only when the data isn't in the HTML or in a JSON call the page makes. Compare the page source with what DevTools shows; if the data arrives via an XHR request, call that endpoint directly. Render only pages that truly need JavaScript, block images and fonts, and reuse browser contexts, because rendering is far slower and costlier.

A headless browser runs the page's JavaScript without a visible window: the most complete way to fetch a page, and the most expensive. Two quick tests tell you whether you need one:

  • Compare view source with Elements. Search the page's source (Ctrl+U or Cmd+Option+U) for a value you want, such as a price. If it's there, a plain HTTP request is enough; if only the DevTools Elements panel shows it, JavaScript built it.
  • Check the Network tab for a Fetch/XHR request carrying the data, like the JSON endpoint example earlier, and call it directly.

If you do need rendering, send only the URLs that fail those tests to the browser, and block images, fonts, and media. With Playwright or a similar tool, run one browser process with a fresh context per job instead of a new browser per page.

Scrapy users can render JavaScript only for the requests that need it and keep the rest of the crawl on Scrapy's fast HTTP downloader.

How do you write parsers that survive layout changes?

Anchor selectors to things that rarely change (ids, data attributes, semantic structure, embedded JSON-LD) instead of styling classes, keep an ordered list of fallback selectors per field, decode the raw bytes correctly, and make missing required fields fail loudly. A parser that silently returns blanks is worse than one that crashes.

Choose selectors that outlast a redesign

Styling classes like .text-lg.font-bold change whenever a designer touches the page. Ids, data-* attributes, itemprop microdata, semantic tags, and JSON-LD blocks change far less, because other code depends on them. Keep selectors short, too, since a full path from <body> breaks when any wrapper div moves.

CSS selectors are easier to read, while XPath can select by text and walk up the tree. XPath vs CSS selectors covers the trade-offs.

Keep ordered fallbacks for every field

Give each field a list of selectors, most specific first, and take the first that matches. The SELECTORS dictionary in the snippet below works this way.

Decode bytes, not guessed text

Watch for the "£" encoding bug. If a server sends Content-Type: text/html with no charset, requests falls back to ISO-8859-1 when it builds resp.text, so a UTF-8 page decodes wrongly, "£" turns into "£", and every price fails to parse. Pass resp.content, the raw bytes, to your parser instead; BeautifulSoup will read the page's own <meta charset>.

Test on saved pages

Save a few real pages as test fixtures. When a selector changes, re-parse the stored raw responses and compare the output before and after.

This snippet turns the book cards on a books.toscrape.com catalog page into typed records, validates each one, and prints a quality report, then feeds the parser a card with a renamed price class to show a layout change being caught.

parse_validate.py

"""Parse defensively, normalize, validate, and report data quality."""
import json
from dataclasses import dataclass, asdict
from datetime import datetime, timezone
from decimal import Decimal, InvalidOperation
from urllib.parse import urljoin

import requests
from bs4 import BeautifulSoup

# Ordered fallbacks: the first selector that matches wins.
SELECTORS = {
    "title": ["h3 a[title]", "h3 a"],
    "price": ["p.price_color", "[itemprop=price]"],
    "availability": ["p.availability", ".instock"],
    "url": ["h3 a[href]"],
}
RATINGS = {"One": 1, "Two": 2, "Three": 3, "Four": 4, "Five": 5}


@dataclass
class Book:
    url: str
    title: str
    price: Decimal
    currency: str
    in_stock: bool
    rating: int | None
    fetched_at: str  # provenance: when this record was fetched (UTC)


def first(card, field):
    for css in SELECTORS[field]:
        node = card.select_one(css)
        if node is not None:
            return node
    return None


def parse_card(card, page_url, fetched_at=""):
    errors = []
    link, title_node = first(card, "url"), first(card, "title")
    price_node, stock_node = first(card, "price"), first(card, "availability")
    title = (title_node.get("title") or title_node.get_text(strip=True)) if title_node else ""
    if not title:
        errors.append("title missing")
    raw_price = price_node.get_text(strip=True) if price_node else ""
    currency = "GBP" if "£" in raw_price else "UNKNOWN"
    try:
        price = Decimal(raw_price.replace("£", "").replace(",", ""))
        if price <= 0:
            errors.append("price not positive")
    except InvalidOperation:
        price = Decimal("NaN")
        errors.append(f"price unparseable: {raw_price!r}")
    rating_node = card.select_one("p.star-rating")
    rating = next((RATINGS[c] for c in (rating_node.get("class", []) if rating_node else [])
                   if c in RATINGS), None)
    if link is None:
        errors.append("url missing")
    book = Book(url=urljoin(page_url, link["href"]) if link else "", title=title, price=price,
                currency=currency, in_stock="in stock" in (stock_node.get_text(" ", strip=True).lower()
                                                          if stock_node else ""),
                rating=rating, fetched_at=fetched_at)
    return book, errors


def scrape(page_url):
    resp = requests.get(page_url, timeout=(5, 30),
                        headers={"User-Agent": "acme-catalogue-bot/0.1 (+mailto:data@example.com)"})
    resp.raise_for_status()
    fetched_at = datetime.now(timezone.utc).isoformat(timespec="seconds")
    # Pass bytes, not resp.text: with no charset in Content-Type, requests guesses
    # ISO-8859-1 and "£" becomes "£". BeautifulSoup reads the page's <meta charset>.
    soup = BeautifulSoup(resp.content, "html.parser")
    cards = soup.select("article.product_pod")
    seen, good, rejected = set(), [], []
    for card in cards:
        book, errors = parse_card(card, page_url, fetched_at)
        if book.url in seen:
            errors.append("duplicate url")
        seen.add(book.url)
        (rejected if errors else good).append((book, errors))
    report = {
        "page": page_url,
        "cards_found": len(cards),
        "valid": len(good),
        "rejected": len(rejected),
        "missing_rating": sum(1 for b, _ in good if b.rating is None),
        "sample": {k: str(v) for k, v in asdict(good[0][0]).items()} if good else None,
    }
    return good, rejected, report


if __name__ == "__main__":
    _, rejected, report = scrape("https://books.toscrape.com/catalogue/page-1.html")
    print(json.dumps(report, indent=2))
    for book, errors in rejected:
        print("REJECTED", book.url, errors)
    # Simulate a layout change: the price class is renamed.
    html = '<article class="product_pod"><h3><a href="x.html" title="T">T</a></h3><p class="cost">£1.00</p></article>'
    card = BeautifulSoup(html, "html.parser").select_one("article")
    print("after layout change:", parse_card(card, "https://books.toscrape.com/")[1])
  • first() walks each field's fallback list, so one renamed class doesn't empty a column.
  • BeautifulSoup(resp.content, ...) passes bytes, which avoids the encoding bug above.
  • parse_card() collects errors instead of raising them, so one bad card doesn't stop the page and every reject has a reason.
  • The simulated layout change returns "price unparseable" instead of a blank price, which is the signal you want in your logs.

More on turning raw pages into fields is in our data parsing guide. On Node.js, the same selector-based parsing shows up in our guide to web scraping with Cheerio.

How do you check the quality of scraped data?

Treat every record as untrusted until it passes a schema: required fields present, correct types, sane ranges, and a unique key. Use Decimal for money, normalize currencies and dates, dedupe on the key, store the source URL and fetch time, and produce a per-run report of valid, rejected, and missing values.

Data quality is where scrapers fail silently: the fetch succeeds, the parser runs, and wrong values flow into reports for weeks. These data scraping best practices stop that:

  • Define the schema in code. The Book dataclass in the parsing snippet is the data contract in Python; pydantic adds more checks, but a dataclass needs no extra dependency.
  • Reject rather than coerce. When a price won't parse, reject the record with its reason instead of storing a zero; reject reasons are your earliest warning of a layout change.
  • Store money as Decimal, never as a float, since floats can't represent most prices exactly. Normalize currencies to ISO 4217 codes and timestamps to UTC.
  • Watch field-level null rates for jumps against the last run.
  • Dedupe on the canonical URL or a business key such as a SKU. Duplicates usually mean a pagination loop or the same item listed in two categories.
  • Give every row a source_url and fetched_at, so any value traces back to its page and moment.
  • Produce a per-run quality report: cards found, valid, rejected, and missing optional fields. The parsing snippet prints exactly this, and the next section monitors it.

Check

Example rule

Catches

Required fields

title and price present

Layout changes

Types

price parses as Decimal

Encoding bugs, wrong selector

Ranges

0 < price < 10,000

Unit or currency mix-ups

Uniqueness

one row per URL

Pagination loops, duplicates

Null rate

rating nulls no more than 5 points above the last run

Partial breakage

Provenance

source_url and fetched_at set

Untraceable records

How do you monitor a web scraper in production?

Track a few run-level metrics and alert on change, not just on crashes: success rate by status code, records per page, empty pages, field null rates, retries, latency, freshness, and cost per valid record. Make the job exit non-zero when thresholds break, so your scheduler, not a customer, notices first.

A crashing scraper is easy to notice; one that quietly collects the wrong thing isn't. Treat the thresholds below as starting points to tune, not benchmarks.

Metric

Why it matters

Example alert

Success rate by status code

Spots blocks and outages

2xx share drops below 95%

Records per page

Spots layout changes

Below 50% of the 7-day median

Empty pages

Silent breakage

Any page with 0 records

Field null rate

Partial breakage

Up 10 points vs the last run

Retries per request

Throttling

Average above 0.3

p95 latency

Server strain

Doubles vs baseline, so slow down

Freshness

Missed runs

Data older than your target

Cost per valid record

Budget drift

Up 25% week on week

Two habits make these metrics more useful:

  • Fetch a few canary URLs with known values, such as a product with a fixed title, on every run. A wrong canary means the parser broke, not the data.
  • Alert on deltas rather than fixed numbers. A drop in records per page against the 7-day median is a better layout-change alarm than any absolute count.

The crawl snippet in the next section ends with a health() function that flags fetch errors, empty pages, and thin pages, then exits with status 1. Schedulers such as cron, systemd, Airflow, and CI runners treat that as a failure, so the alert comes from tools you already run.

For scheduling, delivery, and replay, see how to build scraping jobs you can recover.

How do you scale web scraping without breaking it?

Scale the bookkeeping before the workers, because advanced web scraping techniques like distributed crawling depend on it. Keep a deduplicated URL frontier, commit each page's records and its "done" flag in one transaction, write idempotently so re-runs don't duplicate rows, enforce rate limits per domain across all workers, and crawl incrementally using sitemaps and conditional requests instead of re-fetching everything.

Best practices for scalable web scraping are mostly about state, because more workers multiply whatever is wrong with how you track progress.

  • Use a frontier, not a list: a deduplicated queue of URLs that lets a crawl discover new pages as it goes. New to frontiers? Start with web crawling in Python.
  • Make checkpoints transactional. Commit a page's records, discovered links, and "done" flag in one transaction, so a crash leaves all of that page's work or none of it.
  • Write idempotently. Primary keys or upserts make a duplicate write a no-op, so re-runs and retries are safe.
  • Resume instead of restarting. The next run picks up from the first unfinished URL.

To see it work, crawl quotes.toscrape.com with the snippet below, which keeps a SQLite frontier and commits each page's work in one transaction. Run python resumable_crawl.py 3 to stop after three pages, then run python resumable_crawl.py again: the second run resumes where the first stopped, with no duplicate rows.

resumable_crawl.py

"""Resumable pagination crawl with a SQLite checkpoint and a run health check."""
import json
import sqlite3
import sys
import time
from urllib.parse import urljoin

import requests
from bs4 import BeautifulSoup

START = "https://quotes.toscrape.com/page/1/"
HEADERS = {"User-Agent": "acme-quotes-bot/0.1 (+mailto:data@example.com)"}


def open_db(path="crawl.db"):
    db = sqlite3.connect(path)
    db.executescript("""
        CREATE TABLE IF NOT EXISTS frontier (url TEXT PRIMARY KEY, done INTEGER DEFAULT 0);
        CREATE TABLE IF NOT EXISTS quotes (text TEXT, author TEXT, tags TEXT,
                                           page TEXT, PRIMARY KEY (text, author));
    """)
    db.execute("INSERT OR IGNORE INTO frontier(url) VALUES (?)", (START,))
    db.commit()
    return db


def crawl(db, max_pages):
    stats = {"pages": 0, "errors": 0, "rows": 0, "empty_pages": 0, "rejected": 0}
    while stats["pages"] < max_pages:
        row = db.execute("SELECT url FROM frontier WHERE done = 0 LIMIT 1").fetchone()
        if row is None:
            break  # frontier exhausted
        url = row[0]
        try:
            resp = requests.get(url, headers=HEADERS, timeout=(5, 30))
            resp.raise_for_status()
        except requests.RequestException:
            stats["errors"] += 1
            break  # leave it undone; the next run resumes here
        soup = BeautifulSoup(resp.content, "html.parser")
        quotes = soup.select("div.quote")
        stats["empty_pages"] += not quotes
        with db:  # rows, link discovery and the checkpoint commit together
            for q in quotes:
                text, author = q.select_one("span.text"), q.select_one("small.author")
                if text is None or author is None:
                    stats["rejected"] += 1  # malformed card: reject it, don't coerce
                    continue
                cur = db.execute(
                    "INSERT OR IGNORE INTO quotes VALUES (?, ?, ?, ?)",
                    (text.get_text(strip=True), author.get_text(strip=True),
                     ",".join(t.get_text(strip=True) for t in q.select("a.tag")), url))
                stats["rows"] += cur.rowcount
            nxt = soup.select_one("li.next a[href]")
            if nxt:
                db.execute("INSERT OR IGNORE INTO frontier(url) VALUES (?)",
                           (urljoin(url, nxt["href"]),))
            db.execute("UPDATE frontier SET done = 1 WHERE url = ?", (url,))
        stats["pages"] += 1
        time.sleep(1.0)  # pace requests to one host
    return stats


def health(stats, db, min_rows_per_page=5):
    problems = []
    if stats["errors"]:
        problems.append(f"{stats['errors']} fetch errors")
    if stats["empty_pages"]:
        problems.append(f"{stats['empty_pages']} pages had no records (layout change?)")
    if stats["rejected"]:
        problems.append(f"{stats['rejected']} cards missing text or author")
    if stats["pages"] and stats["rows"] / stats["pages"] < min_rows_per_page:
        problems.append("rows per page below threshold")
    total = db.execute("SELECT COUNT(*) FROM quotes").fetchone()[0]
    pending = db.execute("SELECT COUNT(*) FROM frontier WHERE done = 0").fetchone()[0]
    return {**stats, "total_rows": total, "pending_urls": pending, "problems": problems}


if __name__ == "__main__":
    max_pages = int(sys.argv[1]) if len(sys.argv) > 1 else 100
    db = open_db()
    report = health(crawl(db, max_pages), db)
    print(json.dumps(report))
    sys.exit(1 if report["problems"] else 0)
  • with db: wraps the inserted quotes, the newly found next-page link, and the done = 1 update in one transaction.
  • INSERT OR IGNORE against primary keys makes every write idempotent, for both frontier URLs and quotes.
  • A failed fetch leaves its URL undone and stops the run, so the next run retries it first.
  • Cards missing a quote or author are skipped and counted instead of saved half-empty.
  • health() turns the run's counters into a list of problems, and sys.exit(1) makes those problems visible to whatever schedules the job.

Once the bookkeeping is solid, three more practices add capacity safely:

  • Share per-domain rate limits. Across several machines, local pacing no longer protects the site, so keep one budget per domain in a shared place, such as a token bucket in Redis.
  • Crawl incrementally. Use sitemap lastmod dates to queue only new or changed URLs, and conditional requests to turn unchanged pages into empty 304s.
  • Scale horizontally last. Add workers only once per-host limits are enforced centrally, so more workers mean more hosts in parallel, not more pressure on one.

How do you keep web scraping costs under control?

Measure cost per valid record, not cost per request. Most savings come from fetching less: cache and use conditional requests, prefer JSON endpoints, render only when required, cap retries, use proxies only for hosts that need them, and crawl incrementally. Then compare that number honestly against a managed scraping API before building more.

The formula is simple:

cost per valid record = (infrastructure + proxies + engineering hours) ÷ valid records delivered

Engineering hours belong in the numerator, since a scraper that needs a developer every week isn't cheap. The denominator counts only records that passed validation.

Lever

Effect

See

Conditional requests and caching

Unchanged pages return an empty 304

Request habits

JSON endpoints over HTML

Fewer requests, simpler parsing

Planning

Render only when needed

Avoids browser costs on static pages

Headless browsers

Retry caps and backoff

Stops retry storms

Request rate

Proxies only where needed

Pay for IPs only on hosts that block

Blocks

Incremental crawls

Fetch only new or changed URLs

Scaling

Validation before storage

Don't pay to store or ship bad rows

Data quality

Build or buy

Building in-house makes sense for a few stable, lightly protected targets. When proxies, retries, rendering, and blocks cost more engineering time than the data is worth, compare cost per valid record across the options in our roundup of web scrapers and scraping APIs. If you'd rather not run that infrastructure at all, WebScrapingAPI's Scraper API is a managed scraping API that handles proxies, retries and optional JavaScript rendering. JavaScript rendering and geotargeting cost no extra credits on it, and failed requests aren't billed.

Skip advice that trades short-term access for risk: faking a Googlebot User-Agent, rotating User-Agents on every request with mismatched headers, scripted "random" mouse movements as a default, fixed delays that ignore server signals, retrying every error forever, and scraping everything just in case. Each one adds cost, risk, or bad data.

"Use a Googlebot User-Agent so sites let you in." Site owners can unmask a fake Googlebot with a DNS lookup. Use an honest User-Agent with contact details, as described in the identification section.

"Rotate User-Agents on every request." A browser User-Agent with headers no real browser would send stands out more than a consistent identity, so keep one coherent header set per session.

"Add random mouse movements and clicks to look human." For most targets this adds complexity and slows every page without fixing the usual problem, request volume, so fix your rate and headers first.

"Wait 5 to 10 seconds between requests and you're safe." A fixed delay is too slow for a site that's coping well and too fast for one returning 429s. Use per-host pacing that adapts to latency and Retry-After.

"Retry until it works." Unlimited retries turn one outage into a retry storm. Retry only retryable errors, back off with jitter, and cap the attempts.

"Scrape everything, just in case." Extra pages cost bandwidth, storage, and server time, and extra fields raise your exposure if they hold personal data. Collect what your data contract lists.

"Crawl-delay is a standard everyone follows." It isn't part of RFC 9309, and Google ignores it. Honor it when present, but don't expect every crawler or parser to read it the same way.

"My library handles robots.txt for me." requests and BeautifulSoup don't fetch or apply robots.txt at all. Scrapy can, through its ROBOTSTXT_OBEY setting, which projects created with scrapy startproject turn on. Check your settings, and test the matcher against the rules you depend on.

Web scraping best practices checklist

Before a scraper goes to production, confirm it has a written data contract, a standards-compliant robots.txt check, an honest User-Agent, per-host pacing with Retry-After support, timeouts, conditional requests, fallback selectors, schema validation, run health alerts, transactional checkpoints, and a tracked cost per valid record.

Each row has a "done when" test, so you can tell whether a scraper is ready for production.

Stage

Check

Done when

Plan

Data contract written

Fields, types, key, and freshness agreed

Legal

Terms and robots.txt reviewed

Standards-compliant matcher in the fetch path

Identity

Honest User-Agent

Name, version, and contact URL included

Rate

Per-host pacing

Retry-After honored; backoff with jitter; retry cap set

Requests

Timeouts and sessions

Connect and read timeouts set everywhere

Caching

Conditional requests

ETag and Last-Modified stored and sent

Parsing

Fallback selectors

Bytes passed to the parser; fixtures in tests

Quality

Schema validation

Reject reasons logged; dedupe on key

Monitoring

Run health

Non-zero exit on threshold breach; canaries in place

Scale

Checkpoints

Data and progress commit in one transaction

Cost

Unit economics

Cost per valid record tracked weekly

Building these skills from scratch? Pick from our best web scraping courses.

FAQ

What are web scraping best practices?

Web scraping best practices are the habits that keep scrapers legal, polite, accurate, and affordable. They include collecting only the data you need, following robots.txt and site terms, identifying your bot, pacing each host, honoring Retry-After, validating records, monitoring runs, checkpointing progress, and tracking cost per valid record.

How many requests per second is safe when scraping a website?

No number is safe everywhere. Start with one or two concurrent requests per host, about a second apart, then adapt: slow down as response times rise, pause on 429 or 503 responses, honor Retry-After, and run large crawls off-peak.

Do I have to follow robots.txt when scraping?

Nothing technically stops you, but robots.txt is the owner's published rule for automated clients, and ignoring it invites blocks. Apply it as RFC 9309 defines, using your bot's own group if one exists, and read the site's terms too.

Does Python's robotparser follow the robots.txt standard?

Not fully. Python's urllib.robotparser applies rules in file order instead of picking the longest match, so it can allow URLs a site disallows or block URLs it allows. It also ignores the * and $ wildcards defined in RFC 9309.

Which User-Agent should I use for web scraping?

Use an honest, stable User-Agent that names your bot and gives a contact URL or email, so site owners can reach you instead of blocking you. Never impersonate Googlebot, because Google publishes how to verify its crawlers.

How should a scraper handle a 429 Too Many Requests response?

Stop sending requests to that host, read Retry-After, and wait at least that long; the value is either seconds or an HTTP date. Without the header, back off exponentially with jitter, cap retries, and lower per-host concurrency before resuming.

How do I stop my scraper breaking when a website changes its layout?

You can't prevent redesigns, but you can survive them: anchor selectors to stable hooks such as ids, data attributes, or JSON-LD, keep per-field fallbacks, fail loudly on missing required fields, and alert when records per page drop.

How do I check the quality of scraped data?

Validate every record against a schema before storing it: required fields, correct types, sensible ranges, and a unique key. Use Decimal for prices, dedupe on the key, log reject reasons, and compare null rates and row counts across runs.

Do I need a headless browser for web scraping?

Usually not. If the data is in the page source or in a JSON request in the Network tab, fetch that directly. Use a headless browser only for pages that build their content with JavaScript, and block images and fonts.

How can I make web scraping faster without getting blocked?

Fetch less instead of hammering harder: JSON endpoints instead of rendered pages, conditional requests so unchanged pages return 304, sitemap-driven incremental crawls, and connection reuse. Then parallelize across hosts, not within one, with per-host limits in place.

Is it OK to scrape data behind a login?

Be careful. Logging in usually means accepting the site's terms, many of which prohibit automated access, so treat authenticated areas as off-limits without permission or a contract. With permission, keep credentials in a secrets manager, limit personal data, and respect normal rate limits.

When should I use a web scraping API instead of building my own scraper?

Build in-house when targets are few, stable, and lightly protected. Use a managed scraping API when proxies, retries, rendering, and blocks eat more engineering time than the data is worth, or you need many countries, and compare cost per valid record, engineering hours included.

Spend your time on data, not plumbing

Every practice above is work you can keep in-house, and for many teams that's the right call. When it isn't, you can try the Scraper API with 5,000 free requests and let it handle proxies, retries and optional JavaScript rendering, run dynamic pages through the Browser API with a single REST request, add pay-as-you-go residential proxies from $8.50 per GB, or get structured records from 116 supported sources with the Data API.

About the Author

Anda Miuțescu, Technical Content Writer @ WebScrapingAPI

Anda Miuțescu

Technical Content Writer

Anda Miuțescu is a Technical Content Writer at WebScrapingAPI, creating clear, useful content that helps developers understand the product and its capabilities.

Nodriver Python Tutorial: Stealth Browser Scraping From First Script to Production
Science of Web Scraping

Nodriver Python Tutorial: Stealth Browser Scraping From First Script to Production

TL;DR: Nodriver is an async Python library that drives Chromium over the Chrome DevTools Protocol, with no Selenium or chromedriver binary. Use it when a self-hosted stealth browser closer to a real Chrome session beats a WebDriver stack, but know it doesn't remove IP, TLS, or behavioral risk on its own. This tutorial goes from a first script to containerized production and a hosted Browser API.

Suciu Dan11 min read
Read Article
How to Handle Google /goto Redirect URLs and CAES Tokens in a SERP Scraper
Science of Web Scraping

How to Handle Google /goto Redirect URLs and CAES Tokens in a SERP Scraper

TL;DR: Google /goto URLs with a CAES token, and older /url wrappers, are redirect layers, not destinations, so a SERP scraper that treats every href as final breaks rank tracking and link stores. Prefer a structured SERP API when it returns destination links. When you must parse HTML, classify every href, dedupe redirects, and resolve them with a plain GET. Do not decrypt CAES.

Suciu Dan11 min read
Read Article
HTTP Response Headers in cURL: Every Flag and Recipe
Science of Web Scraping

HTTP Response Headers in cURL: Every Flag and Recipe

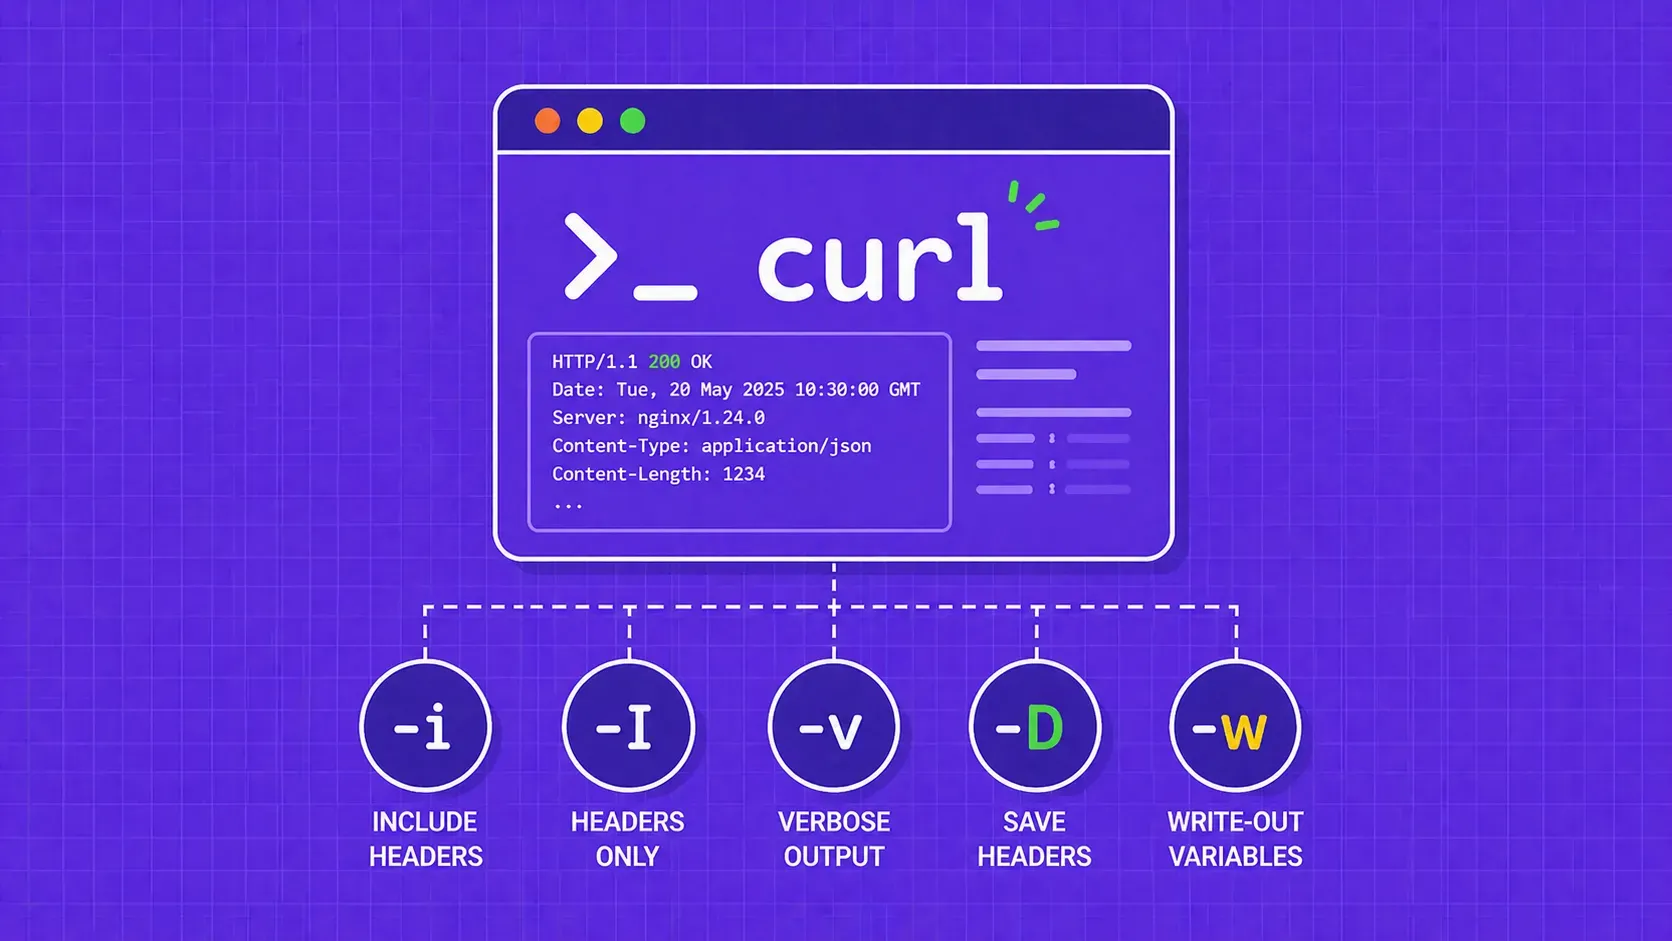
TL;DR: cURL hides response headers by default. Use -i to see headers alongside the body, -I for a HEAD request that returns headers only, -v for full request/response debugging, and -D to save headers to a file. For modern scripting, cURL 7.83+ lets you extract individual headers or dump all of them as JSON with the -w write-out option.

Suciu Dan11 min read
Read Article

Start Building

Ready to Scale Your Data Collection?

Join 2,000+ companies using WebScrapingAPI to extract web data at enterprise scale with zero infrastructure overhead.