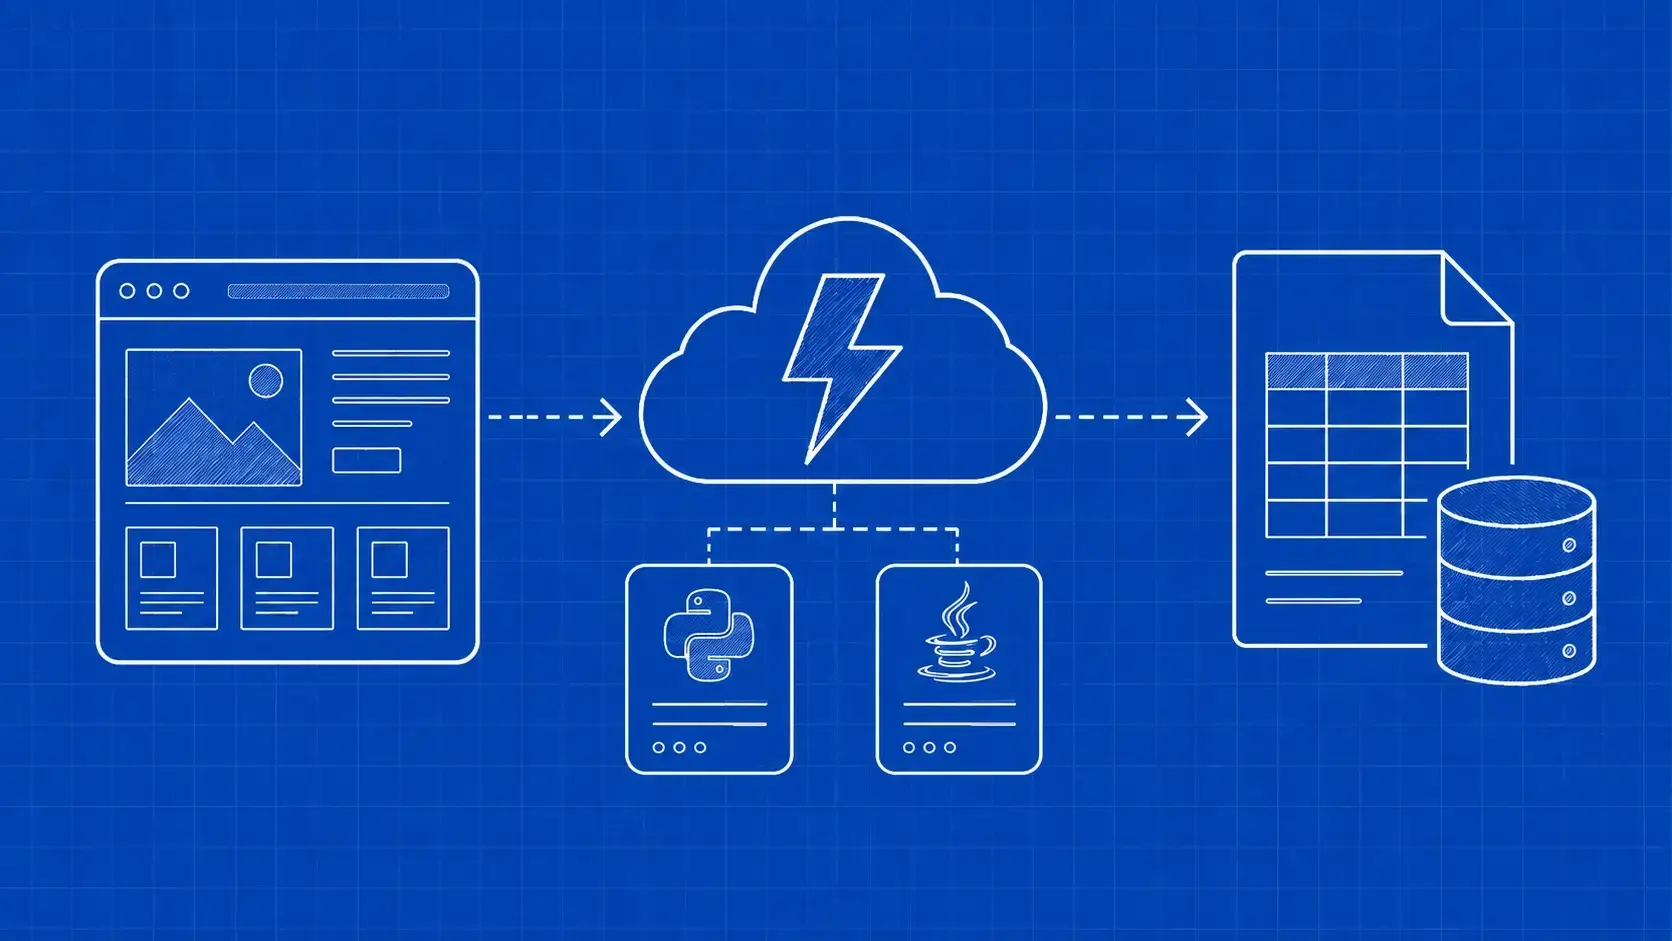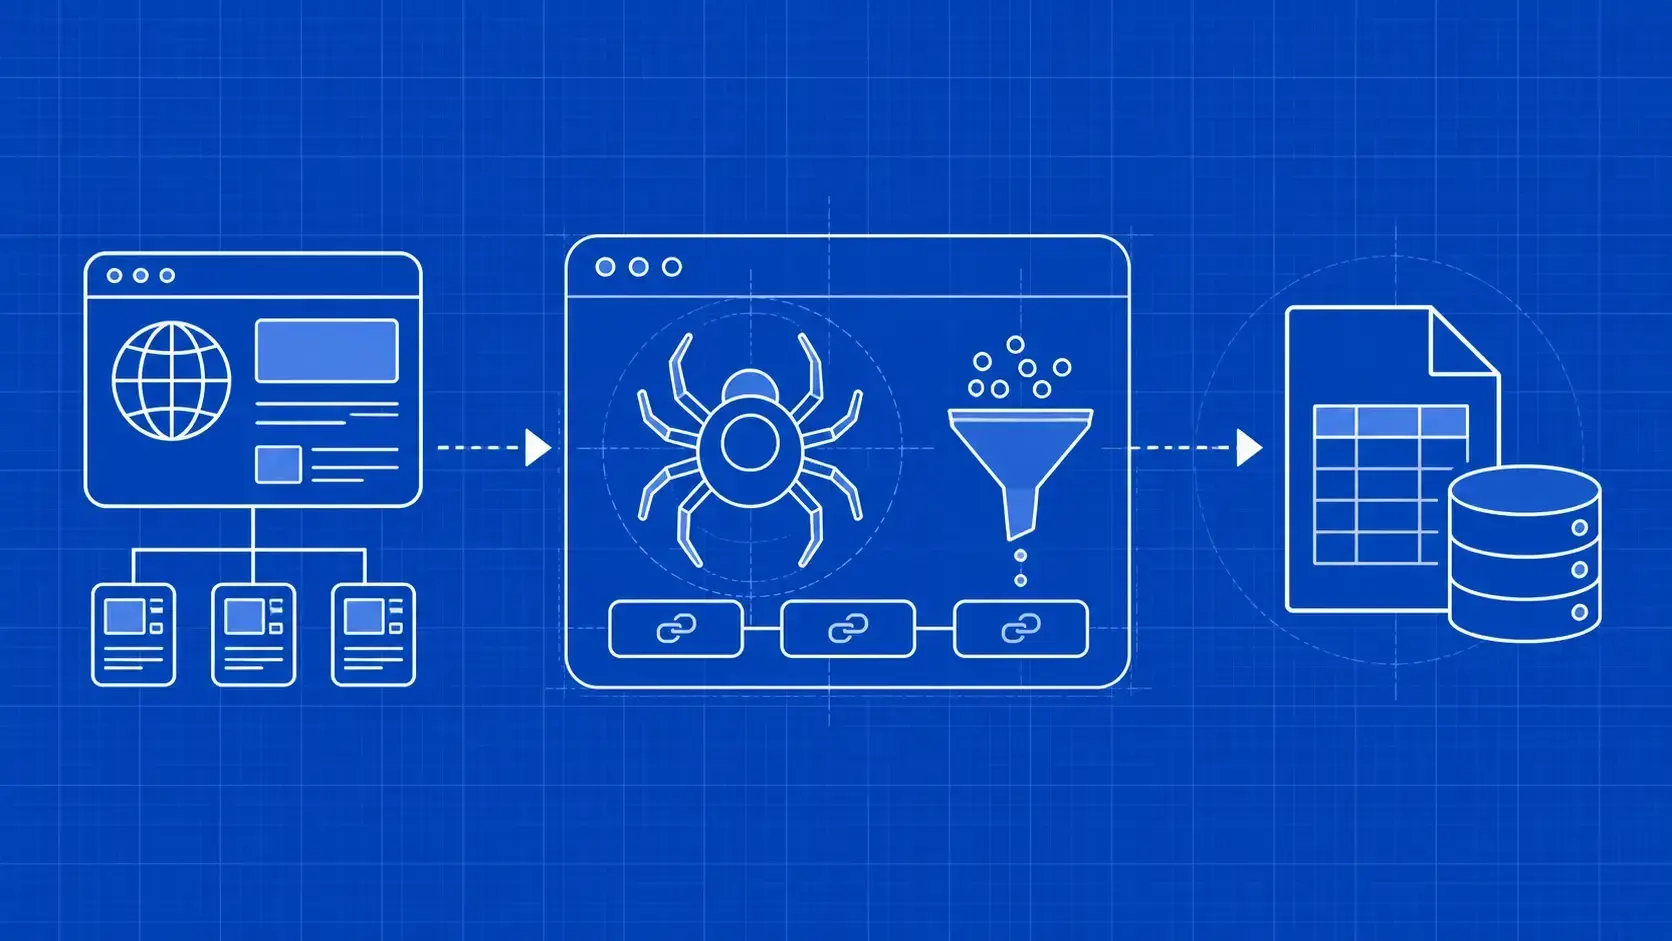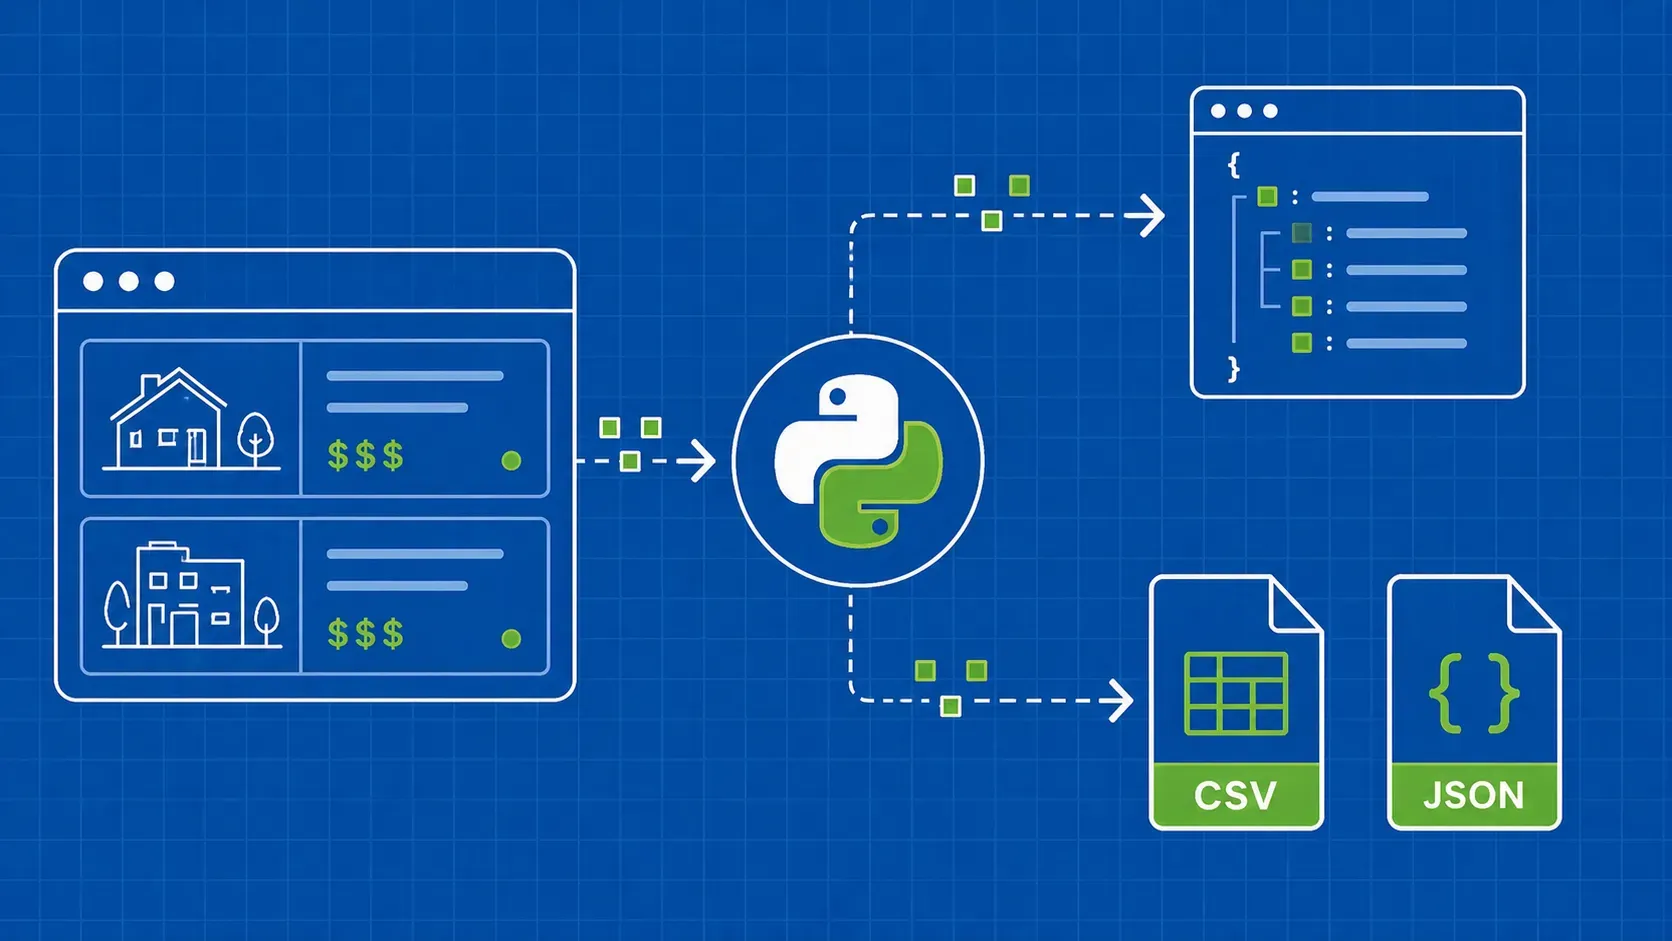
Web scraping with Rust comes down to three crates: reqwest sends the HTTP requests, scraper parses the HTML with CSS selectors, and tokio runs everything asynchronously. You'll build one scraper end to end. It collects every book in books.toscrape.com, a public practice catalog, follows the pagination, fetches pages concurrently with polite limits, retries failed requests, and writes the results to CSV and JSON. Then you'll handle a JavaScript-rendered page (quotes.toscrape.com/js/) three ways: by reading its embedded JSON, by rendering it in headless Chrome, and by calling a scraping API from the same reqwest client.
The code targets the crate versions in the table below, including the feature changes in reqwest 0.13 that break many older tutorials.
Key takeaways
- Use reqwest 0.13 for HTTP, scraper 0.29 for parsing, and tokio for async. Enable reqwest's
queryfeature before calling.query(). - Build one
Clientand reuse it. Build your selectors once, not inside a loop. - Parse HTML in a regular sync function, because
scraper::Htmlcan't be held across an.awaitin a spawned task. - Follow the "next" link for pagination, cap concurrency with
buffer_unordered, and retry 429 and 5xx responses with backoff. - For JavaScript pages, check the raw HTML first, then look for embedded JSON, and only then reach for a headless browser or a managed API.